
as_rtftables() turns a table into a list of
rtftable page objects – one per RTF page – ready
to hand to rtf_tables(). Pagination has three pillars, and
this article is organised around them:
-
How the rows are split into pages – the
split =strategies (and custom / pre-split / hybrid variants). -
Which column those page-shaping operations act on, and what
to do with it – one shared idea behind
group_col,group_by,sort_by,collapse_repeatsanddrop_cols(see Selecting a column). - Blank separator rows – inserting and counting the gaps between groups.
We start with the split strategies:
- the built-in split strategies,
- a custom split function,
- pre-splitting the data yourself, and
- an advanced hybrid that composes a built-in strategy.
Throughout we use a small demographics-style table. By the
clinical-TFL convention, a row whose first column starts with a
non-space character opens a group, and the indented rows below
it are that group’s members – which is how as_rtftables()
detects groups by default (group_col = NULL,
group_by = "auto"). Tables that mark groups differently – a
repeated key column, or a group label with blank member rows – are
handled by group_col / group_by, covered under
Shared knobs below.
Show code
df <- data.frame(
  Parameter = c("Age (years)", "  Mean", "  SD", "  Min", "  Max",
                "Sex",         "  F", "  M",
                "Race",        "  White", "  Black", "  Asian", "  Other"),
  Value     = c("",     "75.1", "8.2", "50", "89",
                "",     "179 (58%)", "127 (42%)",
                "",     "273 (89%)", "29 (9%)", "2 (1%)", "2 (1%)"),
  stringsAsFactors = FALSE
)
A tiny helper to show how a result was paginated – it prints the row-label column of each returned page:
Show code
1. Built-in split strategies
Pass split = one of the built-in strategy names.
"none" (default) – one page
The whole table stays on a single page; no row limit is checked.
pages <- as_rtftables(df)            # split = "none"
length(pages)
#> [1] 1
"rows" – cut at explicit positions
Give split_rows the row numbers at which a new page
should start. Use this when you know exactly where the breaks go.
pages <- as_rtftables(df, split = "rows", split_rows = c(6, 9))
show_pages(pages)
#> --- Page 1 ---
#>   Age (years)
#>     Mean
#>     SD
#>     Min
#>     Max
#>
#> --- Page 2 ---
#>   Sex
#>     F
#>     M
#>
#> --- Page 3 ---
#>   Race
#>     White
#>     Black
#>     Asian
#>     Other
"group_force" – fill max_rows, repeat the
group label on a cut
Pack up to max_rows rows on each page. When a page
boundary falls inside a group, a continuation row is inserted
at the top of the next page repeating the group label with a
" (Cont.)" suffix, so the reader knows the group carries
over.
pages <- as_rtftables(df, split = "group_force", max_rows = 6)
show_pages(pages)
#> --- Page 1 ---
#>   Age (years)
#>     Mean
#>     SD
#>     Min
#>     Max
#>
#> --- Page 2 ---
#>   Sex
#>     F
#>     M
#>   Race
#>     White
#>     Black
#>
#> --- Page 3 ---
#>   Race (Cont.)
#>     Asian
#>     Other
"group_safe" – never break a group across pages
Pack whole groups onto a page; a group that would overflow
is pushed to the next page instead of being split. (A single group
larger than max_rows is still force-split as a
fallback.)
pages <- as_rtftables(df, split = "group_safe", max_rows = 6)
show_pages(pages)
#> --- Page 1 ---
#>   Age (years)
#>     Mean
#>     SD
#>     Min
#>     Max
#>
#> --- Page 2 ---
#>   Sex
#>     F
#>     M
#>
#> --- Page 3 ---
#>   Race
#>     White
#>     Black
#>     Asian
#>     Other
"by_value" – one page per group, named by the
group
Emit exactly one page per detected group; the returned list is
named by the group label (which
rtf_tables() can use, e.g. with
auto_section = TRUE).
pages <- as_rtftables(df, split = "by_value")
names(pages)
#> [1] "Age (years)" "Sex"         "Race"
Reusing a strategy
Earlier versions also exported a page_split_*() factory
per strategy, so a configured splitter could be built once and passed
around. They were retired before the first release: a factory carried
its own group_col, which meant the group column could be
declared in two places at once, and the two did not always agree. Every
setting now has exactly one place to live – alongside split
– so reuse is a list of arguments rather than an object:
Shared knobs
These arguments shape pagination regardless of the strategy:
| Argument | Effect |
|---|---|
max_rows |
Maximum data rows per page (required for the group strategies). |
group_col |
Which column groups are detected on: a name, a 1-based
index, or NULL for column 1. |
group_by |
How a group boundary is found on group_col:
"auto", "indent", "value", or
"filled" (see below). |
min_group_rows |
Widow/orphan control: avoid stranding a lone group header (or too
few of its rows) at a page boundary. Set 0 to disable. |
cont_label |
The continuation suffix (" (Cont.)") repeated on a
mid-group cut. |
Selecting a column
Five arguments operate on one column of the rendered body, and they all name that column the same way – by a column name or a 1-based integer index, in the body’s coordinate space:
| Argument | What it does to the column |
|---|---|
group_col |
detects group boundaries on it (with group_by) |
sort_by |
orders the rows by it, before the split |
collapse_repeats |
blanks consecutive repeated values in it |
drop_cols |
hides it from the printed pages |
Because they share one coordinate space, the same key works across
them – e.g. sort on a column, group on it, and hide it:
as_rtftables(x, sort_by = "k", group_col = "k", drop_cols = "k").
Two things make the name source-dependent, so they are worth repeating here:
-
It is the body column id, not the visible header. A
gtsummary
stat_1column shows as “Drug (N = …)” but is selected as"stat_1". -
The names differ by source – your own for a
data.frame, gt ids for gt / gtsummary / tfrmt, andV1,V2, … for rtables / flextable / huxtable. An integer index is the most portable choice across sources. Check the actual names withnames(as_rtftables(x)[[1]]$data). The full per-source table and check recipes are in What the columns are called.
Choosing how groups are detected – group_by
group_col picks the column;
group_by picks the logic used to find where one
group ends and the next begins on that column:
group_by |
A row starts a new group when its group_col cell … |
|---|---|
"indent" |
is non-empty and does not start with whitespace (space / tab / non-breaking space); indented or empty cells are members. This is the usual clinical row-label layout. |
"value" |
differs from the row above it (each maximal run of equal values is one group). |
"filled" |
is non-empty; NA / "" cells belong to the
group above (the label appears once, on the group’s first row). |
"auto" |
(default) picks one from the column’s content: indentation present →
"indent"; else empty cells interspersed →
"filled"; else → "value". |
Show code
# Group by a repeated key column (value), regardless of indentation.
df_key <- data.frame(
  Visit = c("Week 1", "Week 1", "Week 2", "Week 2", "Week 4"),
  Result = c("12", "0.3", "14", "0.4", "11")
)
pages <- as_rtftables(df_key, split = "group_safe", max_rows = 2,
                      group_col = "Visit", group_by = "value")
length(pages)                                  # one page per Visit block
#> [1] 3
Show code
# A group label on its first row, blank members below it (filled).
df_filled <- data.frame(
  Group = c("Group A", "", "", "Group B", ""),
  Value = c("", "1.2", "3.4", "", "5.6")
)
pages <- as_rtftables(df_filled, split = "group_safe", max_rows = 3,
                      group_by = "filled")
length(pages)
#> [1] 2The grouping column need not be the first column – name it (or, for portability across sources, give its integer index; see Selecting a column):
Show code
df2 <- data.frame(
  Parameter = c("ALT", "AST", "ALT", "AST"),
  Visit     = c("Week 1", "Week 1", "Week 2", "Week 2"),
  Value     = c("12", "20", "14", "22")
)
pages <- as_rtftables(df2, split = "group_safe", max_rows = 2,
                      group_col = 2L, group_by = "value")   # group on Visit
length(pages)
#> [1] 2Ordering rows before the split – sort_by /
sort_desc
group_col chooses where the breaks fall, but it
does not reorder anything – the body is split in the order it arrives.
sort_by orders the body rows before
pagination, so group detection, the " (Cont.)" labels and
any blank_rows positions all see the sorted order. Name one
or more sort keys (in the input body’s coordinates, the same space as
group_col and drop_cols), with optional
per-key direction via sort_desc.
Show code
df_s <- data.frame(
  Region = c("West", "East", "West", "East"),
  Site   = c("S2",   "S1",   "S1",   "S2"),
  N      = c("12",   "9",    "20",   "4")
)
# Region ascending, then Site ascending.
as_rtftables(df_s, sort_by = c("Region", "Site"))[[1]]$data[c("Region", "Site")]
#> Region Site
#> 1 East S1
#> 2 East S2
#> 3 West S1
#> 4 West S2sort_desc is a single TRUE (all keys
descending) or one logical per key:
# Region ascending, Site descending.
as_rtftables(df_s, sort_by = c("Region", "Site"),
             sort_desc = c(FALSE, TRUE))[[1]]$data$Site
#> [1] "S2" "S1" "S2" "S1"
#> "S2" "S1" "S2" "S1"
The sort is stable (rows that compare equal keep
their input order) and NA keys sort last,
regardless of direction. It is meant for flat / tabular bodies – a
data.frame, or a pre-flattened table; a gt / rtables body
whose group-label and child rows are already interleaved should be
sorted at the source (before the table is built), since
reordering its rendered rows would scramble that hierarchy. To mix name
and index keys, pass a list().
A sort key is often a column you do not want printed
– a numeric ordering key, a raw priority. Combine sort_by
with drop_cols
to order on it and then hide it:
Show code
df_c <- data.frame(
  soc_ord = c(2, 1, 2, 1),                  # hidden ordering key
  Term    = c("Rash", "Angina", "Pruritus", "Failure"),
  N       = c("9", "12", "4", "7")
)
res <- as_rtftables(df_c, sort_by = "soc_ord", drop_cols = "soc_ord")[[1]]$data
names(res)            # the key is gone
#> [1] "Term" "N"
res$Term # but the rows are ordered by it
#> [1] "Angina" "Failure" "Rash" "Pruritus"
#> [1] "Angina" "Failure" "Rash" "Pruritus"Blanking repeated values – collapse_repeats
A "value"-style column carries the group key on
every row, but tables usually print the key only once per run
and leave the repeats blank – the "filled" layout.
collapse_repeats performs exactly that conversion: name one
or more columns and each run of equal values is suppressed to a single
visible cell, the rest replaced with NA (which renders as
an empty cell – no row is removed, only the text is hidden).
Show code
df_rep <- data.frame(
  Group = c("All", "All", "BORC", "BORC", "BORC", "BORC",
            "HOGE", "HAGE", "HOGE", "HAGE", "HAGE")
)
as_rtftables(df_rep, collapse_repeats = "Group")[[1]]$data$Group
#> [1] "All" NA "BORC" NA NA NA "HOGE" "HAGE" "HOGE" "HAGE"
#> [11] NA
#> "All" NA "BORC" NA NA NA "HOGE" "HAGE" "HOGE" "HAGE" NAWhere does this sit relative to group_by? It runs
after value-based grouping and before
the table is shown as "filled": the suppression is applied
per page, after the split, so the pagination still sees
the original repeated values. Group boundaries and the
" (Cont.)" continuation labels stay correct, and a group
continued onto the next page shows its label again at the top of that
page (each page restarts the suppression).
Several columns are suppressed hierarchically: the first listed column is collapsed on its own value, and each later column on the combination of itself with all earlier listed columns – so a change in any higher column restarts the lower column’s run.
Show code
df_hier <- data.frame(
  Soc = c("Cardiac", "Cardiac", "Cardiac", "Vascular", "Vascular"),
  Pt  = c("Angina",  "Angina",  "Failure", "Angina",   "Angina")
)
res <- as_rtftables(df_hier, collapse_repeats = c("Soc", "Pt"))[[1]]$data
res$Pt   # row 3 keeps "Failure"; row 5 blanks the repeated "Angina" under Vascular
#> [1] "Angina" NA "Failure" "Angina" NA
#> "Angina" NA "Failure" "Angina" NAHiding a grouping / carrier column – drop_cols
group_col chooses which column drives the split, but
that column is normally printed too. Often you want to break or
group on a key that should not appear in the report – a
numeric ordering key, a raw group id, a sort helper.
drop_cols names columns (in the input body’s coordinates –
the same space as group_col and
collapse_repeats) that are kept through
the split and then removed from every page before it is
rendered.
Show code
df_carrier <- data.frame(
  soc_ord = c(1, 1, 2, 2),                  # hidden ordering / group key
  Term    = c("Angina", "Failure", "Rash", "Pruritus"),
  N       = c("12", "7", "9", "4")
)
# Group + page on the hidden key, but print only Term + N.
pages <- as_rtftables(df_carrier, split = "by_value",
                      group_col = "soc_ord", drop_cols = "soc_ord")
names(pages)                 # pages still named by the group value: "1", "2"
#> [1] "1" "2"
names(pages[[1]]$data) # the carrier column is gone: "Term", "N"
#> [1] "Term" "N"
#> [1] "Term" "N"The column is present while the split runs – so
group_col, collapse_repeats, and
blank_rows_by_change() can all reference it – and only then
dropped. All position-indexed metadata (column headers, including
spanning headers; col_spec; column widths;
col_header_align; row_title; per-cell
cell_styles) is reindexed automatically to the columns that
remain, so explicit headers/widths you pass for the full table still
line up after the hide.
A few interactions worth knowing:
-
drop_cols,group_col, andcollapse_repeatsall index the pre-drop input body. - For
split = "by_value"the page names come from thegroup_colvalue, so that column can be hidden and the pages are still named by it (above). - Under
"group_safe"/"group_force"the" (Cont.)"marker is written into thegroup_colcell. If you hide that very column the marker is removed with it, so group on the visible label column when you want the continuation label to show. -
drop_colsmust leave at least one column to display.
To mix column names and integer indices, pass a
list() (a plain c() would coerce to one type):
drop_cols = list("soc_ord", 3).
2. A custom split function
When the built-ins don’t fit, pass a function as
split =. It is called on the (cell-formatted) body and must
return a list of data.frames – one per page. Named list
elements become page names, exactly like "by_value".
Show code
#> [1] 4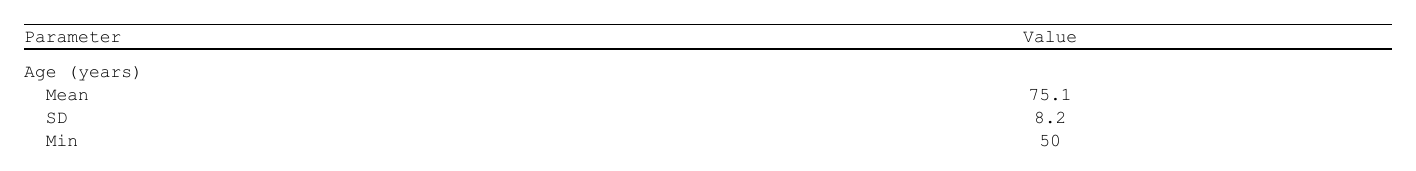
Your function only implements the split; the rest of the pipeline
(blank rows, metadata, per-page assembly, and header/width/style
replication) is applied to its output unchanged. Write it with a
... so it tolerates the context arguments
(max_rows, group_col, group_by,
cont_label, min_group_rows) it does not
use.
To re-create the " (Cont.)" continuation row the
built-in group strategies add, use add_cont_label():
Show code
by_four_cont <- function(df, cont_label = " (Cont.)", ...) {
  parts <- split(df, (seq_len(nrow(df)) - 1L) %/% 4L)
  for (i in seq_along(parts)) {
    if (i > 1L) parts[[i]] <- add_cont_label(parts[[i]], "…continued",
                                             cont_label = cont_label)
  }
  parts
}
show_pages(as_rtftables(df, split = by_four_cont))
#> --- Page 1 (0) ---
#> Age (years)
#> Mean
#> SD
#> Min
#>
#> --- Page 2 (1) ---
#> …continued (Cont.)
#> Max
#> Sex
#> F
#> M
#>
#> --- Page 3 (2) ---
#> …continued (Cont.)
#> Race
#> White
#> Black
#> Asian
#>
#> --- Page 4 (3) ---
#> …continued (Cont.)
#> Other3. Two levels at once – page_by
group_col says where a group boundary
is; page_by says where a page boundary is,
and what the page is called. Different jobs, so different arguments –
and together they express the layout a clinical table usually wants: a
BY variable (period, cohort, analysis set) owns the page, while an inner
group (a parameter block) is kept whole inside it.
Show code
as_rtftables(
  lab,
  page_by   = "period",      # new page when it changes; the value is the name
  split     = "group_safe",  # from here on: inside one period only
  group_by  = "indent",
  max_rows  = 20,
  drop_cols = "period"       # page_by does not imply dropping the column
)
#>  "Period 1"  "Period 1"  "Period 2"  "Period 2"  "Period 3"
The body is partitioned on runs of the page_by value
first; every other pagination setting then applies within one
partition – split, max_rows,
group_col, group_by,
min_group_rows, cont_label,
blank_rows, collapse_repeats.
split = "by_value" on its own cannot do this: the group it
protects is the BY column itself, so a parameter block inside a period
is cut wherever max_rows happens to fall.
Every page a partition makes carries the same
heading – the page_by value – because a
page name is what rtf_tables(auto_section = TRUE) /
auto_title = TRUE prints. A section opens where the heading
changes, so one partition is one section of however
many pages it needed, with nothing to clean up.
The names themselves stay unique: a heading used by
several pages carries a "...n" tail, so the list can still
be addressed by name (R returns the first match for a repeated
name – which is what pages[["Period 1"]] and RStudio’s
View() would otherwise show you). The tail is not part of
the heading.
Show code
pages <- as_rtftables(lab, page_by = "period", split = "group_safe",
                      group_by = "indent", max_rows = 20, drop_cols = "period")
names(pages)
#>  "Period 1...1"  "Period 1...2"  "Period 2...1"  "Period 2...2"

doc |> rtf_tables(pages, auto_section = TRUE)   # 2 sections headed "Period 1" / "Period 2"
Two details worth knowing:
-
group_colleftNULLdefaults to the first column not named inpage_by. Without that it would be column 1 – the BY column, where every row of a partition carries the same value andgroup_by = "indent"finds no structure at all. -
naandcell_formatrun body-wide, before the partition, so one column width is shared by every page;split_rows,blank_rowspositions andcount_blank_rowsare resolved inside each partition.
The three axes compose in one pipeline – pages by BY value, then rows, then columns:
as_rtftables(lab, page_by = "period", split = "group_safe",
             group_by = "indent", max_rows = 20, drop_cols = "period") |>
  paginate_cols(at = 6, order = "down")
With split = "by_value" the split makes a page per
group value, and then the group is the
outer axis with page_by inside it – a
group’s pages stay together, the BY values running in order, and every
page of the group carries the group’s name:
as_rtftables(ae, split = "by_value", group_col = "cohort", page_by = "period",
             drop_cols = c("cohort", "period"))
#>  "Cohort A"  "Cohort A"  "Cohort B"  "Cohort B"
The two values are never joined into one name: the name is the
section heading, so "Cohort A / P1" would cut each cohort
into a section per period. Both stay readable per page in
attr(page$data, "rtf_paginate_meta")
(page_group, page_by).
Add paginate_cols() and the column block takes its place
between them or under them, as order says (see Which
axis the page number advances along): "across" gives
group / column block / page_by, "down" gives
group / page_by / column block.
4. Pre-splitting the data yourself
Sometimes the simplest thing is to split the data.frame
before calling as_rtftables() and hand it a list.
as_rtftables() flattens a list input into one page per
element, carrying the list’s names through as page names.
Show code
top    <- df[1:8, ]
bottom <- df[9:13, ]

pages <- as_rtftables(list("Demographics (1 of 2)" = top,
                           "Demographics (2 of 2)" = bottom))
names(pages)
#> [1] "Demographics (1 of 2)" "Demographics (2 of 2)"This is handy when the split rule lives in your own data-wrangling
code (for example split(df, df$SOC) for a list of
adverse-event tables), or when each page comes from a different source
entirely.
5. Advanced: post-processing a built-in split
A custom split = function can run the built-in machinery
first and then adjust its output – a hybrid of approaches 1 and 2. The
simplest way is to call as_rtftables() for the split and
post-process the pages:
pages <- as_rtftables(df, split = "group_safe", max_rows = 6)
pages <- Filter(function(p) nrow(p$data) > 0L, pages)   # keep non-empty pages
length(pages)
#> [1] 3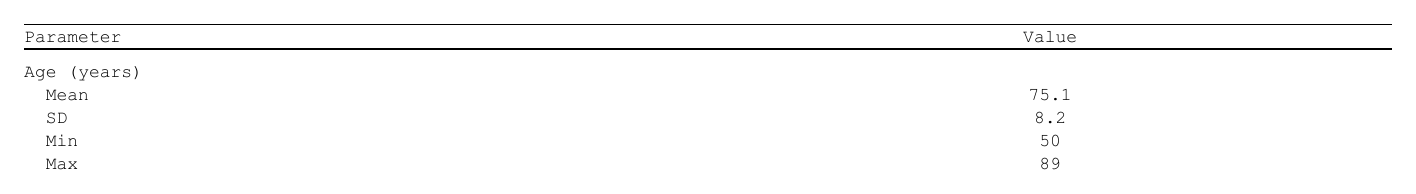
Blank separator rows
Clinical tables often need blank separator rows – empty rows that put a little air between groups. They are not part of the data; they are layout, added on top of the body.
Blank rows and the row count
This matters for pagination: max_rows counts
data rows only. Blank rows are inserted into each page
after the split, so they do not use up the
max_rows budget. For example, packing whole groups with
max_rows = 6 and a blank between groups:
Show code
df_g <- data.frame(
  label = c("Group A", "  a1", "  a2", "Group B", "  b1", "  b2",
            "Group C", "  c1", "  c2"),
  v = as.character(1:9), stringsAsFactors = FALSE
)

pages <- as_rtftables(df_g, split = "group_safe", max_rows = 6,
                      blank_rows = "between_groups")
nrow(pages[[1]]$data)          # 6 data rows -- the max_rows budget
#> [1] 6
pages[[1]]$blank_rows # plus a blank after row 3 (A -> B), not counted
#> [1] 3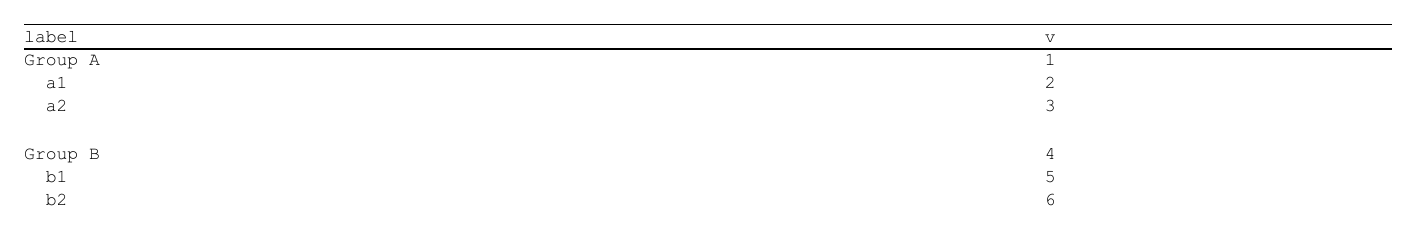
So page 1 shows six data rows and a separator –
seven rows on the page – but only the six data rows counted toward
max_rows.
To make the blanks count – so a page (data + blanks) never exceeds
max_rows – set count_blank_rows = TRUE. The
blank positions are then resolved on the full table and counted during
the split (a leading blank is suppressed at the top of each page):
pages2 <- as_rtftables(df_g, split = "group_safe", max_rows = 6,
                       blank_rows = "between_groups", count_blank_rows = TRUE)
vapply(pages2, function(p) nrow(p$data) + length(p$blank_rows), integer(1))
#> [1] 3 3 3
Every page now fits within six rows. (blank_row_first /
blank_row_end below are page furniture added after
the split and are never counted, so they may still push a page past
max_rows.)
Adding blank rows while paginating
as_rtftables() takes the blank-row controls alongside
the split arguments; they are applied to every page:
-
blank_rows = "between_groups"– a blank at each group transition on a page; -
blank_rows = c(0, 3)– explicit positions (0= before the first row,k= after rowk), relative to each page; -
blank_row_first = TRUE/blank_row_end = TRUE– a blank at the top / bottom of every page.
Paginating yourself: set_blank_rows()
set_blank_rows() is the helper
as_rtftables() calls on every chunk. If you do your own
splitting, use it to attach the blank positions to a page-sized
data.frame; rtftable(read_attributes = TRUE) (the default)
then picks them up:
page <- set_blank_rows(df_g, blank_rows = "between_groups")
attr(page, "rtf_blank_rows")
#> [1] 3 6
tbl <- rtftable(page)          # read_attributes = TRUE consumes the attribute
Blank rows on a single (un-paginated) table
You do not need pagination to use them:
rtftable(blank_rows = ) accepts integer positions (here
-1 also means “after the last row”), or the spec
constructors [blank_rows_by_change()] (blank when a column value
changes) and [blank_rows_by_rule()] (blank before/after rows matching a
regex), or a list combining them:
rtftable(df_g, blank_rows = blank_rows_by_change("label"))
#> ──────────
#> label    v
#> ──────────
#> Group A  1
#>   a1     2
#>   a2     3
#> Group B  4
#>   b1     5
#>   b2     6
#> Group C  7
#>   c1     8
#>   c2     9
#>
#> <rtftable> 9 rows x 2 columns
#>   Row title:  col 1
#>   Borders:    set
#>   Widths:     auto / inherited
Control the separator height with blank_row_height_twips
(e.g. half the data row height); see Page
& document setup. The full spec forms are documented in
?rtftable and ?set_blank_rows.
Normalising blank rows – blank_row_normalize
Two render-time clean-ups are applied to blank rows by default,
controlled by the single blank_row_normalize argument (on
rtftable(), and forwarded by as_rtftables() /
rtf_tables()):
| token | effect |
|---|---|
"detect" |
a data row whose every cell is NA /
"" (empty or ASCII-whitespace only) is rendered as a single
full-width blank row – like an explicit separator – instead of one empty
cell per column (which would draw the internal column rules across the
gap). |
"collapse" |
a run of two or more consecutive blank rows (separators and/or detected empty rows) is reduced to a single blank row. |
The default is c("detect", "collapse") – the combination
wanted for most clinical TFLs. Because both act on the rendered
table, they apply per page for a paginated table
(i.e. after the split), so a stray empty row left at a page edge, or two
separators meeting at a group boundary, collapse cleanly. Pass
"none" (or NULL) to switch the normalisation
off and render blank data rows verbatim:
Show code
df_b <- data.frame(
  A = c("x", "", "", "y"),     # two adjacent all-empty rows
  B = c("1", "", "", "2"),
  stringsAsFactors = FALSE
)
rtftable(df_b)                                   # default: one blank row
#> ────
#> A B
#> ────
#> x 1
#>
#>
#> y 2
#>
#> <rtftable> 4 rows x 2 columns
#> Row title: col 1
#> Borders: set
#> Widths: auto / inherited
rtftable(df_b, blank_row_normalize = "none") # keep both empty data rows
#> ────
#> A B
#> ────
#> x 1
#>
#>
#> y 2
#>
#> <rtftable> 4 rows x 2 columns
#> Row title: col 1
#> Borders: set
#> Widths: auto / inheritedNote "detect" only fires when all
columns are empty; an NBSP-indented label (the clinical sub-row layout)
is not whitespace-empty, so indented rows are never mistaken for
blanks.
Splitting the other way: paginate_cols()
Everything above cuts rows. A table that is too
wide needs the other axis: paginate_cols() splits
it by column and repeats the row-heading column(s) on
every page.
as_rtftables(df, split = "group_safe", max_rows = 20) |>
  paginate_cols(at = c(4, 6))
at names the columns to cut before (so
c(4, 6) gives blocks 1:3, 4:5,
6:ncol), symmetric with split_rows;
cols = list(2:3, 4:5) states the blocks outright. Positions
refer to the final printed columns – after
drop_cols, stub and any
col_header you supplied – the same convention
set_col_header() follows.
Row splitting happens first and the column split is applied to its result, so by default the row page is the outer level: a row band sweeps every column block before the next band starts, so the reader goes across the table first and then down it. Two row pages by three column blocks come out as
page 1  row 1 / cols 1    page 4  row 2 / cols 1
page 2  row 1 / cols 2    page 5  row 2 / cols 2
page 3  row 1 / cols 3    page 6  row 2 / cols 3
Which axis the page number advances along – order
order says which axis the page number advances
along first: "across" (the default) advances
across the columns – the column block first, the row
pages running inside it – and "down" advances down
the rows – the row page first, its column blocks following
it.
as_rtftables(df, split = "group_safe", max_rows = 20) |>
  paginate_cols(at = c(4, 6), order = "down")
"across" "down"
page 1 cols 1 / row 1 page 1 row 1 / cols 1
page 2 cols 1 / row 2 page 2 row 1 / cols 2
page 3 cols 2 / row 1 page 3 row 2 / cols 1
page 4 cols 2 / row 2 page 4 row 2 / cols 2The pages themselves are identical under either setting – only their
order differs – so pick the one your deliverable reads in:
"down" when a reader follows a row band across the sheet,
"across" when each column block is a self-contained table
read on its own.
Those two are shorthands. In general order names the
axes of the split, in the order they nest – outermost
first:
| axis | what it is |
|---|---|
"group" |
the pages a value-based split made
(as_rtftables(split = "by_value", group_col = )) |
"rows" |
the row pages: page_by, and every other row split |
"cols" |
the column blocks paginate_cols() cuts |
paginate_cols(pages, at = c(4, 6), order = c("group", "cols", "rows"))
paginate_cols(pages, at = c(4, 6), order = c("cols", "group", "rows"))
paginate_cols(pages, at = c(4, 6), order = "cols")        # cols first, rest as usual
"across" is c("group", "cols", "rows") and
"down" is c("group", "rows", "cols"). An axis
left out is appended in the default order ("group",
"rows", "cols"), and an axis the table does
not have never varies – so the same call works whether or not
group_col / page_by were used. Each page
records its own group (in rtf_paginate_meta$page_group), so
the sort never has to read a page name.
One consequence: rtf_tables(auto_section = TRUE) opens a
section where the page name changes, and a page is
named by its group. A group’s pages are one section only while
"group" comes first; put "cols" outside it and
every column block starts the groups again, giving a section per block
and group.
One thing to know about the names: a page’s name
follows the row page it was cut from, so under "across"
pages that share a name are no longer adjacent – and that does
reach the sections, because rtf_tables(auto_section = TRUE)
opens a section where the name changes.
"down" therefore keeps a table’s column pages in one
section, while "across" interleaves the names and gives a
section per page. An unnamed page list (what
as_rtftables() returns for a single table) opens none at
all. To put pages whose names differ in one section, blank the
ones that should not open a new one – combine_sections()
does that bookkeeping.
The columns repeated on each page default to the table’s
row_title (column 1 unless you set it); keep =
overrides that, and keep = integer(0) repeats nothing. A
kept column is removed from the blocks automatically, so it is never
printed twice on one page.
A header whose values change per page –
set_col_header(values = )
A header is usually one shape with a few values that change page to
page – (N=120) for one period, (N=118) for the
next. Write it once, with a {token} where
a value belongs, and give set_col_header() a table of
values keyed by the page:
Show code
hdr <- rtf_col_header(
  list(col_cell(1L, ""),
       col_cell(c( 2L,  9L), "Placebo
(N={n_pbo})
n(%)"),
       col_cell(c(10L, 17L), "TAK-003
(N={n_trt})
n(%)")),
  c("Parameter", rep(VISITS, 2))
)

vals <- data.frame(
  group = c("Period 1", "Period 2", "Period 3"),
  n_pbo = c(120, 118, 238),
  n_trt = c(115, 112, 227)
)

as_rtftables(lab, split = "by_value", group_col = "period", ...) |>
  set_col_header(hdr, values = vals) |>
  paginate_cols(cut_by = "____", keep = 1)
The key column is named after the axis it matches,
the vocabulary order uses: group (default –
the value a "by_value" page was cut for), rows
(the page_by value) or name (the page’s unique
name); several may be combined. The keys live in the page’s metadata, so
they survive drop_cols and the column split.
Mistakes are errors, not silently wrong headers: a page with no row,
a row no page used, or a token with no value all stop the call and name
what is missing. header_map() shows what every page ended
up with:
Where to cut, and what the header says – cut_by /
col_header
at, and cut_by given a list of blocks, are
positions. When the grouping is already in the column
names – the common wide layout, one column per treatment x
visit – cut_by reads it from there: give it the separator,
and the part before it becomes the block key.
as_rtftables(df, split = "by_value", group_col = "period",
             stub = c("row_grp1", "label")) |>
  paginate_cols(cut_by = "____", keep = 1, col_header = "names")
col_header = "names" then builds the two-level header
those names already carry – the key on top, the rest of the name
below:
page 1                            page 2
|            |   Placebo     |    |            |   HOGE-001    |
| Group      | D1 | D2 | D8  |    | Group      | D1 | D2 | D8  |
cut_by also takes one key per column
when the grouping is not in the names.
A header written for the whole table goes in the same argument and is sliced per page (spanning cells clipped):
paginate_cols(pages, at = c(11, 19), keep = 1, col_header = HDR) # HDR = every labelWrite the header before or at the split, never after
it: a page keeps only its own columns, so a full-table header no longer
fits it, and set_col_header() says so rather than printing
the first labels on every page.
Column widths after the split – fit
column_widths_twips is absolute: a subset already
carries the right widths and nothing is rescaled.
Relative widths need a rule, because
.compute_cellx() re-normalises whatever it is given across
the page – a bare subset would stretch the kept columns to refill the
sheet, making a ratio-1 column a different size on every page.
fit = TRUE (the default) fixes the twips per
ratio unit on page 1 and reuses it everywhere. Page 1 – and
every block with the same ratio total – fills the sheet, while a given
ratio is the same width throughout. With
rel = c(3, 1, 1, 1, 1, 1, 1, 1, 1) on a 13680-twip
page:
| blocks | unit | page widths |
|---|---|---|
| 4 + 4 | 1954.3 | 100% / 100% |
| 4 + 3 | 1954.3 | 100% / 85.7% |
| 2+2+2+2 | 2736.0 | 100% on all four |
Show code
tbl <- rtftable(df, col_rel_width = c(3, rep(1, 8)))
paginate_cols(tbl, at = 6)
# page 1: 5863 1954 1954 1954 1955   (13680 -- full)
# page 2: 5863 1954 1954 1954 1955   (13680 -- full)
fit = FALSE measures against the whole table instead, so
a kept column has exactly the width it had before the split and a
partial block yields a proportionally shorter page:
paginate_cols(tbl, at = 6, fit = FALSE)
# page 1: 3731 1244 1244 1244 1242   (8705 -- 64% of the sheet)
Order the blocks widest-first. A block totalling
more ratio than block 1 scales past the sheet under
fit = TRUE – three visits then five, say, puts page 2 at
133% of the width. paginate_cols() warns and names the
blocks; either reorder the cut or use fit = FALSE.
Spanning header cells are clipped to each page’s columns. By default
a cut may fall inside a spanning group, and that group’s label is
repeated over its remaining columns on both pages; pass
allow_span_break = FALSE to reject such a cut instead and
be told which cell it would break.
Page names are carried through unchanged: each column page keeps the
name of the row page it was cut from (see Which axis is the outer
level above for what auto_section then does with
them).
Worked example: a PK concentration summary
data-raw/gen_pk_conc.R builds the case that needs all of
this at once – a pharmacokinetic concentration table with the
visits across the columns, so it is too wide
and too tall for one page:
Show code
# ABSOLUTE widths, from what the cells actually need
widths <- auto_col_widths(pk, col_header = names(pk))

as_rtftables(
    pk,
    split = "group_safe", group_by = "indent", max_rows = 21,
    col_header = list(
      list(col_cell(c(2, length(VISITS) + 1), "Plasma Concentration (ng/mL)")),
      c("Nominal Time (h)", VISITS)
    ),
    column_widths_twips = widths,
    border = "tfl"
  ) |>
  set_decimal_split(cols = VISITS) |>   # one column, two cells
  paginate_cols(at = length(VISITS) / 2 + 2)   # visits cut down the middle
Three time bands by two visit blocks gives six pages, each with the nominal time stub, and every visit column the width it has in the full table.
Size the table from its content, not from the page
Note the column_widths_twips rather than
col_rel_width. Relative widths cannot produce a
table that needs paginate_cols():
.compute_cellx() normalises them across the page, so
whatever the ratios the full table comes out exactly as wide as the
sheet, and the split would be decorative. auto_col_widths()
reports what the content needs instead:
stub "Nominal Time (h)"   2021 twips   (widest cell "Min, Max")
each visit column         1804 twips   (widest cell "496.28, 1461.8")
so only six visits fit on a landscape sheet’s 13680 writable twips.
The study has twelve, which makes the table
2021 + 12 x 1804 = 23669 twips – 1.73x too wide to
fit – and each half 2021 + 6 x 1804 = 12845, or
94% of the page. That is what the example should look
like: a table that genuinely cannot be printed in one piece, cut into
blocks that each fill the sheet.
as_rtftables(auto_width = TRUE) is deliberately not used
here: it clamps the total to the writable width when the natural size
exceeds it, squeezing the columns back onto one page.
What the split does to the numbers
PK reports carry three significant figures, so the decimal count
changes with the magnitude (1104.5, 88.012,
9.0125) – set_decimal_split() lines the points
up regardless, <0.500 hangs its < to the
left of the point, and BLQ or a Min, Max pair
falls back to a single merged cell.
One consequence is worth knowing: the split decision is made
per page. A visit column that is all BLQ
within one time band carries no decimal separator there, so that page
leaves the column unsplit while the other pages split it. Each page
stays internally consistent, which is what the geometry needs.
Choosing an approach
| You want… | Use |
|---|---|
| Everything on one page |
split = "none" (default) |
| Breaks at known row numbers |
split = "rows" + split_rows
|
| As many rows as fit, groups may split (with a continuation label) |
split = "group_force" + max_rows
|
| As many whole groups as fit, never split a group |
split = "group_safe" + max_rows
|
| One page per group, named | split = "by_value" |
| One page per BY value, and an inner group kept whole |
page_by + split = "group_safe" +
max_rows
|
| A bespoke rule | a custom split = function (+
add_cont_label()) |
| The split already done upstream | pass a (named) list to as_rtftables()
|
| A built-in rule plus a tweak | split with a built-in, then post-process the pages |
| The table is too wide for the page |
paginate_cols() (after the row split) |
Whichever you choose, the result is the same shape – a list of
rtftable pages – so the rest of your pipeline does not
change:
Show code
doc <- rtf_document() |>
  rtf_section(page = 1, header = NULL, footer = NULL) |>
  rtf_tables(as_rtftables(df, split = "group_safe", max_rows = 6))

generate_rtfreport(doc, "demographics.rtf", overwrite = TRUE)
See ?as_rtftables for the full split =
contract and ?page_split for the factory functions.
Where next
- Output options — rendering the pages you just cut
The four recipes (?rtfreporter-recipes) are the same
ground covered as runnable help-page examples: demographics, adverse
events, PK and laboratory, each data-in to RTF-out.