
A tfrmt table with several stub columns: one for sections, the rest as a stub
Source:vignettes/articles/multistub-section-split.Rmd
multistub-section-split.RmdWhen a tfrmt
table places its row-group levels in columns –
row_grp_plan(label_loc = element_row_grp_loc(location = "column"))
– each grouping variable becomes its own stub column in
the resulting gt. A very common clinical layout then wants
to treat those stub columns in two different ways at
once:
-
one stub column drives page / section
splitting (one section per lab test, per cohort, …), its value
dropped into the running header via
rtf_tables(auto_section = TRUE); - the remaining stub columns are merged into a single indented row heading (the clinical “stub”).
This article shows both, on a lab toxicity-grade table whose three stub columns are lab test code (LBTESTCD -> sections), a fixed heading, and Toxicity Grade (the last two -> a two-level indented stub).
The data
A tidy toxicity-grade summary: for each lab test and grade, a
percentage per arm. heading is a constant column – it
becomes the fixed top level of the stub.
Show code
set.seed(1)
tests  <- c("ALT", "AST")
grades <- c("Grade 0", "Grade 1", "Grade 2", "Grade 3")
arms   <- c("Placebo", "Active")

dat <- expand.grid(LBTESTCD = tests, Toxgrade = grades, ARM = arms,
                   stringsAsFactors = FALSE)
dat$heading <- "Toxicity Grade"
dat$param   <- "pct"
dat$value   <- round(runif(nrow(dat), 1, 40), 1)
dat <- dat[c("LBTESTCD", "heading", "Toxgrade", "ARM", "param", "value")]
head(dat)
#> LBTESTCD heading Toxgrade ARM param value
#> 1 ALT Toxicity Grade Grade 0 Placebo pct 11.4
#> 2 AST Toxicity Grade Grade 0 Placebo pct 15.5
#> 3 ALT Toxicity Grade Grade 1 Placebo pct 23.3
#> 4 AST Toxicity Grade Grade 1 Placebo pct 36.4
#> 5 ALT Toxicity Grade Grade 2 Placebo pct 8.9
#> 6 AST Toxicity Grade Grade 2 Placebo pct 36.0Build the tfrmt table (three stub columns)
group = vars(LBTESTCD, heading) plus
label = Toxgrade, rendered with
location = "column", makes all three row
variables stub-type columns.
Show code
library(tfrmt)

tf <- tfrmt(
  group  = vars(LBTESTCD, heading),
  label  = Toxgrade,
  column = ARM,
  param  = param,
  value  = value,
  body_plan = body_plan(
    frmt_structure(group_val = ".default", label_val = ".default", frmt("xx.x"))
  ),
  row_grp_plan = row_grp_plan(
    label_loc = element_row_grp_loc(location = "column"))
)

g <- print_to_gt(tf, dat)
The gt’s boxhead confirms the three stub columns (plus
the two arm columns and one hidden helper tfrmt adds):
bx <- g[["_boxhead"]]
data.frame(var = as.character(bx$var), type = as.character(bx$type))
#>                   var    type
#> 1            LBTESTCD    stub
#> 2             heading    stub
#> 3            Toxgrade    stub
#> 4             Placebo default
#> 5              Active default
#> 6 ..tfrmt_row_grp_lbl  hidden
gt::extract_body() cannot read a table with more than
one stub column, so as_rtftables() reads such a table from
the gt object’s own slots. There the first
stub column (LBTESTCD) is renamed to "rowname"; the other
stub columns keep their names (heading,
Toxgrade). That is the name you reference below (an
integer index – group_col = 1 – is equally
portable).
One call: split by test, merge the rest into a stub
Show code
pages <- as_rtftables(
  g, read_meta = TRUE,
  # 1) sections: split by the LBTESTCD stub column (now called "rowname"),
  #    then hide it from the printed table (it names the section instead).
  split      = "by_value",
  group_col  = "rowname",
  drop_cols  = "rowname",
  # 2) stub: fold the remaining two stub columns into one indented heading.
  stub       = stub_spec(c("heading", "Toxgrade"), label = "Toxicity Grade"),
  border     = "tfl"
)

names(pages)          # one page per lab test -> section names
#> [1] "ALT" "AST"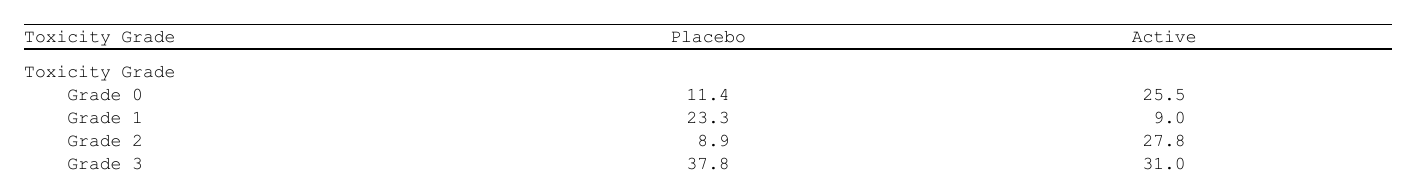
Each page carries the fixed "Toxicity Grade" heading
flush-left, with the grades indented beneath it – the two stub columns
merged into one:
Show code
#>   Toxicity Grade Placebo Active
#> 1 Toxicity Grade    <NA>   <NA>
#> 2    ....Grade 0    11.4   25.5
#> 3    ....Grade 1    23.3    9.0
#> 4    ....Grade 2     8.9   27.8
#> 5    ....Grade 3    37.8   31.0
Hand the named list to rtf_tables(auto_section = TRUE) –
each name becomes a section that starts on its own page with the test
code in the running header:
Show code
doc <- rtf_document() |>
  rtf_section(header = my_header, footer = my_footer) |>
  rtf_tables(pages, auto_section = TRUE)

generate_rtfreport(doc, "lab-tox.rtf", overwrite = TRUE)
Why the order matters
For split = "by_value", as_rtftables()
splits the body first and builds the stub per page.
That order is essential here because the heading level is
constant across the whole table: if the stub were built
first (on the full body), that constant level would collapse into a
single heading row spanning both tests, which could not then be
divided into per-test sections. Splitting first gives each section its
own copy of the heading. (For every other split the table stays one
logical table paginated across pages, so the stub is built once, up
front – see vignette("pagination").)
Consequently, under split = "by_value" the
group_col names a pre-stub column (here
"rowname" = LBTESTCD) and is not one of
the stub columns: the outer level splits, the inner levels
merge.
See also
-
vignette("section-splitting")– getting section names whereauto_sectioncan see them, for every table object. -
vignette("importing-tables")– whatas_rtftables()reads from agt(and why a multi-stub table is read from slots). - [
stub_cols()] – the same stub merge on a plaindata.frame, and thestubargument of [as_rtftables()] that folds it into the pipeline. ```
Where next
- Pagination — how the rows are cut into pages
The four recipes (?rtfreporter-recipes) are the same
ground covered as runnable help-page examples: demographics, adverse
events, PK and laboratory, each data-in to RTF-out.