
Importing tables with as_rtftables()
Source:vignettes/articles/importing-tables.Rmd
importing-tables.RmdThe second path. This article is about bringing a table you already have. When the statistics are in a cards / cardx ARD, the recommended route is a table plan – see Get started and Tables from an ARD.
as_rtftables() is the single entry point for turning a
table object into the rtftable page
objects that rtf_tables() consumes. It does two jobs:
- Read the source table – its rendered body plus the metadata the RTF renderer can use (column labels, alignment, spanning headers, titles, footnotes, …);
-
Paginate – split the body into one
rtftableper page.
This article covers the reading / conversion side. Pagination has its own guide: see Paginating with as_rtftables().
Show code
df <- data.frame(
  Parameter = c("Age (years)", "  Mean", "  SD"),
  Placebo   = c("", "75.1", "8.2"),
  Active    = c("", "74.4", "7.9"),
  stringsAsFactors = FALSE
)

pages <- as_rtftables(df)     # a list of rtftable page objects
length(pages)
#> [1] 1
class(pages[[1]])
#> [1] "rtftable"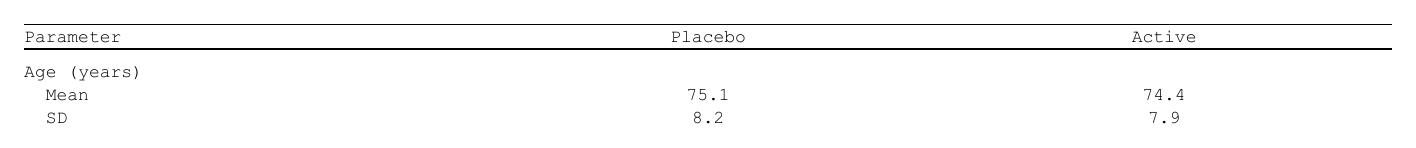
Supported inputs
as_rtftables() accepts any of:
- a
gttable (gt::gt(...)), - a
gt_group– gt’s multi-table container fromgt::gt_group()/gt::gt_split(), and what tfrmt’sprint_to_gt()returns when the spec has apage_plan. Each member table becomes its own page set, so a paginated tfrmt render can be handed over as-is, - a gtsummary table (
tbl_summary(),tbl_regression(), …; converted viagtsummary::as_gt()). Atbl_splitcontainer (tbl_split_by_rows()/tbl_split_by_columns()) is likewise expanded, one member per page set, - an rtables / tern
VTableTree, - a
flextabletable (flextable::flextable(...)), - a
huxtabletable (huxtable::huxtable(...)), - a plain
data.frame/ tibble, or - a
listof any of these (flattened to one page each, names propagated).
It always returns a list of rtftable
objects. For a single table where you do not need a list, use the
singular convenience wrapper as_rtftable() – it is exactly
as_rtftables(x, split = "none")[[1]]:
tbl <- as_rtftable(df)        # one rtftable, not a list
class(tbl)
#> [1] "rtftable"
Being a single-table wrapper, as_rtftable() accepts a
gt_group or a gtsummary tbl_split only when it
holds exactly one table; a multi-member container errors and points you
to as_rtftables().
What the columns are called (and how to check)
Several as_rtftables() arguments select a column
by name or position – group_col
(grouping), sort_by (ordering), drop_cols
(hiding) and collapse_repeats (repeat suppression), all
covered in Paginating with
as_rtftables(). They all act on the rendered
body – the intermediate data.frame that
as_rtftables() builds – not on the visible column
headers. What that body’s columns are called depends on the
source, and this is the single most common stumbling block, so
it is worth knowing the rule up front.
| Source | Body column names | Naming rule |
|---|---|---|
data.frame / tibble |
your own column names | exactly what you named them |
gt (gt(df)) |
gt’s column ids (default: the original data names) | follows gt |
| gtsummary |
label, stat_1, stat_2, … |
gtsummary’s internal ids |
| tfrmt |
rowname, then the column values |
gt stub id + your column levels |
| rtables / tern |
V1, V2, V3, … |
positional, content-independent |
| flextable |
V1, V2, V3, … |
positional |
| huxtable |
V1, V2, V3, … |
positional |
Two families fall out of this:
-
gt-based sources (gt, gtsummary, tfrmt) keep
meaningful id names – but each family’s convention
differs (gt = the data names, gtsummary =
label/stat_N, tfrmt =rowname+ your column levels). -
rtables / flextable / huxtable discard the names
and renumber the columns
V1,V2, … – the name tells you nothing about the content, only the position.
The universal check
Whatever the source, the body column names are exactly
names(as_rtftables(x)[[1]]$data) – the same thing the
selection arguments see. When in doubt, print it:
names(as_rtftable(df)$data)            # a data.frame keeps its own names
#> [1] "Parameter" "Placebo"   "Active"
library(gtsummary)
tbl <- tbl_summary(trial[c("age", "grade")], by = NULL)
names(as_rtftables(tbl)[[1]]$data)     # gtsummary -> "label", "stat_0"
#> [1] "label"  "stat_0"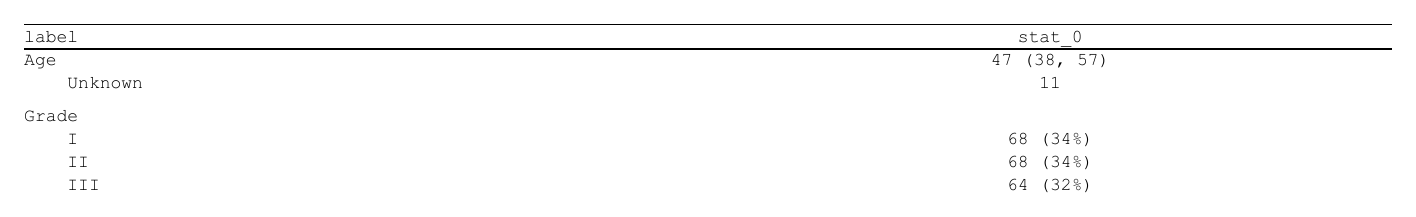
Source packages also offer their own inspectors:
gtsummary’s show_header_names() lists the
internal column names (label, stat_1, …) that
you pass here, and gt’s gt::extract_body()
shows the rendered body with its ids.
Names are carried verbatim, including ones that are
not syntactic R names. A gt column called Drug A (N=60)
arrives as Drug A (N=60) – spaces, parentheses and a
leading digit and all – so select it with that string, and backtick it
where R needs a name rather than a string:
pages |> set_col_header(c(`Drug A (N=60)` = "Drug A"))
as_rtftables(g, drop_cols = "2024 total")
(Before v0.7.54 these were passed through make.names()
and arrived as Drug.A..N.60. / X2024.total,
which is what this section always said they did not do; see #458.)
Two practical rules
Use the id, not the visible header. A gtsummary
stat_1column may display as “Drug (N = …)”, but you must select it as"stat_1". Passing the on-screen label fails with “column not found”.-
Integer indices are the most portable. Because rtables / flextable / huxtable expose only
V1,V2, …, and the gt families differ, a 1-based position works identically across every source:as_rtftables(x, group_col = 1, sort_by = 1, drop_cols = 1) # "the 1st column"Reach for names when they are stable and readable (your own
data.frame, or a known gtsummary layout); reach for indices when writing source-agnostic code.
Reading metadata – read_meta
For a rich source (gt / gtsummary / rtables / flextable / huxtable),
as_rtftables() reads the render-relevant metadata so you do
not have to restate it. What is carried:
| Metadata | gt / gtsummary | rtables / tern | flextable | huxtable |
|---|---|---|---|---|
| Column (leaf) labels | yes | yes | yes | yes |
| Per-column alignment | yes | yes | yes | yes |
| Spanning headers | yes | yes | yes | yes |
| Column widths | yes (px/pct) | – | – | – |
| Title + subtitle | yes | yes | yes (caption) | yes (caption) |
| Footnotes / source notes | yes | yes | yes (footer) | – |
| In-cell footnote marks | yes (superscript) | yes (superscript) | – | – |
| Row-group rows + indent | yes (rendered) | yes (rendered) | yes (rendered) | yes (rendered) |
For flextable the displayed text is read
(header labels from set_header_labels() and
colformat_*() formatting included), not the raw
$body$dataset. Image/equation cells and
footnote() reference marks are not carried.
For huxtable the displayed text is read
with its number_format applied; header rows
(header_rows()) become the column header,
colspan() becomes the spanning header, and the
caption() becomes the page title. huxtable has no footnote
concept, so none is extracted.
Not carried (RTF cannot reproduce them, so they are
intentionally ignored): per-cell bold / italic / underline, cell
background fills, font/size styling, and Markdown inside labels or
titles. A plain data.frame / tibble carries two pieces of
metadata: column label attributes become
header labels (see Finishing a plain data.frame below), and
delimited column names are reconstructed into a
spanning header (see header_sep); everything else
(col_spec, widths, …) you set yourself (see
Pass-through below).
read_meta controls the extraction:
-
TRUE(default) – read everything in the table above. -
FALSE– use only the rendered body (ignore labels / titles / notes). - a character vector of tokens – selective opt-in,
e.g.
c("col_header", "alignment"). Tokens for gt/gtsummary:"col_header","alignment","spanning","widths","titles","footnotes". For rtables/tern:"col_header","alignment","spanning","titles","footnotes","indent","footnote_marks". For flextable:"col_header","alignment","spanning","titles","footnotes". For huxtable:"col_header","alignment","spanning","titles". For a plain data.frame / tibble:"labels"(columnlabelattributes as header labels); unknown tokens are ignored for data.frames, so alist()mixing table objects and data.frames can share oneread_meta.
Show code
library(gt)

g <- gt(head(mtcars[, c("mpg", "cyl")], 3)) |>
  cols_label(mpg = "Miles/gallon", cyl = "Cylinders") |>
  cols_align("right", columns = c(mpg, cyl))

tbl <- as_rtftable(g)               # reads the labels + alignment
tbl$col_header                       # -> "Miles/gallon", "Cylinders"
#> [[1]]
#> [1] "Miles/gallon" "Cylinders"
Show code
# read_meta = FALSE keeps only the rendered body and ignores the labels, so no
# col_header metadata is extracted (the body's own column names are used).
plain <- as_rtftable(g, read_meta = FALSE)
plain$col_header        # NULL -- nothing extracted
#> NULL
names(plain$data) # the body column names that headers fall back to
#> [1] "mpg" "cyl"A flextable is read the same way. The
displayed text is taken (so set_header_labels()
relabelling and colformat_*() formatting are honoured),
along with the caption (title), footer lines (footnotes), spanning
headers and per-column alignment:
Show code
library(flextable)

ft <- flextable(data.frame(Param = c("Mean", "SD"), Value = c(75.13, 8.234))) |>
  set_header_labels(Param = "Characteristic") |>
  colformat_double(j = "Value", digits = 1) |>
  align(j = "Value", align = "right", part = "body") |>
  set_caption("Table 1: Demographics")

tbl <- as_rtftable(ft)
tbl$data[[2]]            # -> "75.1", "8.2"  (colformat applied)
#> [1] "75.1" "8.2"
attr(tbl, "rtf_titles") # -> "Table 1: Demographics" (from the caption)
#> [1] "Table 1: Demographics"
A huxtable works the same way – its
number_format is applied, header rows become the column
header, and the caption becomes the title:
Show code
library(huxtable)

hx <- huxtable(
  Characteristic = c("Characteristic", "Age (years)"),
  Value          = c("Value", 75.134),
  add_colnames = FALSE
)
header_rows(hx)[1]    <- TRUE          # row 1 is the column header
number_format(hx)[2, 2] <- "%.1f"      # 75.134 -> 75.1
caption(hx) <- "Table 1: Demographics"

tbl <- as_rtftable(hx)
tbl$data[[2]]            # -> "75.1"  (number_format applied)
#> [1] "75.1"
attr(tbl, "rtf_titles") # -> "Table 1: Demographics" (from the caption)
#> [1] "Table 1: Demographics"
Numeric columns – format them first
rtfreporter renders the text it is given. A column that is still
numeric when it reaches the renderer is converted with
as.character(), and that is rarely what a report wants:
as.character(1/3)       #> "0.333333333333333"   -- 15 digits
as.character(100000)    #> "1e+05"               -- scientific notation
Worse, the result follows the session’s options(scipen):
as.character(123456) is "123456" under
scipen = 100 and "1.23456e+05" under
scipen = -100. The same code and data would render
differently on different machines.
So convert numbers to their display text before
building the table. fmt_signif() counts the total printed
digits including the integer part – what a SAP means by “report
to 4 significant digits”, which is not what signif()
does:
fmt_signif(c(0, 10.2, 103.4, 20.333333, 23.4463), digits = 4)
#> "0.000" "10.20" "103.4" "20.33" "23.45"
fmt_round() fixes the decimal places instead. Both take
rounding = "sas" for half-away-from-zero rounding, next to
R’s default banker’s rounding – they disagree on exact halves
(23.445 is "23.44" under "r",
"23.45" under "sas"), which matters when the
output is checked against SAS.
fmt_numeric() applies either across a data frame. A
clinical column holds several statistics with different formats, so
by names a carrier column whose values
pick the rule – and it can be the row-heading column itself, matched
after trimming, so an indented " Mean" keys on
"Mean":
Show code
pk |>
  fmt_numeric(
    cols = visit_cols, by = "Nominal Time (h)",
    formats = list(
      n        = list(digits = 0),
      Mean     = list(signif = 4),
      SD       = list(signif = 4),
      `CV%`    = list(digits = 1),
      .default = list(signif = 4)
    )) |>
  as_rtftables(...) |>
  set_decimal_split(cols = visit_cols)
Rows whose selected cells are all missing need no rule, so
group-label and blank rows look after themselves; a non-missing cell
with no matching rule and no .default is an error rather
than a silent 15-digit number.
Character columns are taken as already formatted and
are never touched – including by cols, which skips any
non-numeric column it selects.
Format before splitting: set_decimal_split() measures
the text it is given, so the decimal-point ratio is computed from
"0.3333" rather than from
"0.333333333333333".
Monospaced alignment – cell_format
Clinical tables often need count/percent columns to line up by
character. cell_format re-formats the body
before pagination, column by column. Pass a single
formatter (applied to every data column; the row-label column 1 is left
alone) or a list of them taken positionally. rtfreporter ships a
few:
-
fmt_count_paren()– right-justify an integer count and the number inside the parentheses, e.g."10 (11.6%)"over" 4 ( 4.7%)"; -
fmt_count_paren(bare = TRUE)– the same, and a bare count with no parentheses (a lone"0", a raw total) is padded into the same field; -
fmt_value_paren()– the general form: the value before the parenthesis may be any text ("n=3","3/12", a word), the(...)block is right-justified the wayfmt_count_pct()does it (the padding falls before the(, never inside the parentheses), and a zero count prints without its parentheses; -
fmt_right_align()– the minimal “right-justify a column” formatter and a template for writing your own; -
align_count_pct = TRUE– the long-standing shorthand for the built-in"n (xx.x)"realigner.
A formatter is either the function or its
name as a string, with the fmt_ prefix
optional – handy when the choice comes from a config file or a recipe
rather than from code:
as_rtftables(x, cell_format = "value_paren")
as_rtftables(x, cell_format = list(NULL, "right_align", my_fmt))
as_rtftables(x, align_count_pct = "count_paren")   # the switch takes a name too
Show code
counts <- data.frame(
  Group = c("A", "B"),
  n_pct = c("4 (4.7%)", "10 (11.6%)"),
  stringsAsFactors = FALSE
)
tbl <- as_rtftable(counts, cell_format = fmt_count_paren)
tbl$data$n_pct                       # both cells padded to one width
#> [1] " 4 ( 4.7%)" "10 (11.6%)"fmt_value_paren() is the one to reach for when a column
mixes shapes – a plain N, a count with a percentage, a zero, a text
value:
Show code
mixed <- data.frame(
  Group = c("N", "Responders", "  Mild", "  Severe"),
  stat  = c("86", "12 (100)", "6 (50.0)", "0 (0.0)"),
  stringsAsFactors = FALSE
)
as_rtftable(mixed, cell_format = "value_paren")$data$stat
#> [1] "86 " "12 (100)" " 6 (50.0)" " 0 " 86
12 (100) <- no decimals: flush against the ")"
6 (50.0)
0 <- a zero count prints on its ownWriting your own cell_format function
When none of the built-ins matches your data’s notation, write your own. The contract is small:
-
Signature. The framework calls your function with
one argument – a character vector holding the cells of
a single column. (The built-ins also accept a second
nbsp =argument with a default, butcell_formatnever passes it, so a plainfunction(x)is enough.) Your function is called once per column, and is not told which column it is, so base every decision onxalone. -
Return value. A character vector of the
same length as
x– one element per row. Returning a different length is an error; never drop or add rows. - Leave non-matching cells alone. Cells you do not intend to touch – empty group-label cells, totals, anything not matching your pattern – must be returned unchanged.
-
Pad with the non-breaking space
" ", not a normal space. RTF and Word collapse runs of ordinary spaces, which would silently undo your alignment. -
Which columns it sees. A single function
is applied to columns
2..ncol(column 1 is the row label, left alone by clinical convention). To target specific columns, pass a list instead:cell_format[[j]]formats columnj, andNULLentries leave a column untouched.
Here is a complete formatter that appends a unit and right-aligns a numeric column, leaving blanks and non-numbers as they are:
Show code
# Right-align a numeric column and append a unit (e.g. "mg"), padding on the
# left with non-breaking spaces so the values line up in a monospaced font.
fmt_with_unit <- function(x, unit = "mg", nbsp = " ") {
  x <- as.character(x)
  is_num <- grepl("^[0-9]+(\\.[0-9]+)?$", trimws(x))   # which cells to touch
  labelled <- x
  labelled[is_num] <- paste0(trimws(x[is_num]), " ", unit)
  width <- max(nchar(labelled[is_num]), 0L)            # widest labelled cell
  out <- x
  out[is_num] <- formatC(labelled[is_num], width = width)   # right-justify
  gsub(" ", nbsp, out, fixed = TRUE)                   # protect the padding
}

dose <- data.frame(
  Arm  = c("Low", "High", "Total"),
  Dose = c("5", "12.5", ""),                           # blank cell left as-is
  stringsAsFactors = FALSE
)

# A list targets one column by position; column 1 (Arm) is left untouched.
tbl <- as_rtftable(
  dose,
  cell_format = list(NULL, function(x) fmt_with_unit(x, unit = "mg"))
)
tbl$data$Dose
#> [1] " 5 mg" "12.5 mg" ""Because cell_format passes only the column vector, wrap
a parameterised formatter in a one-argument closure
(function(x) fmt_with_unit(x, unit = "mg")) to fix its
extra arguments – exactly as shown above.
Column widths – auto_width
By default columns share the width evenly. With
auto_width = TRUE each column is sized to its widest
content (header label or data cell) so long labels do not wrap; the
widths are computed once and applied to every page:
tbl <- as_rtftable(df, auto_width = TRUE)
tbl$column_widths_twips
#> [1] 1479 1046  938
Add table_width_twips = to scale those widths to a total
(e.g. to fill, or fit within, the writable page width). An explicit
column_widths_twips / col_rel_width always
wins over auto_width.
Pass-through to rtftable()
Any further argument is forwarded to [rtftable()] for every page, so you can set the table’’s appearance in the same call – and your explicit values always win over the metadata extracted from the source:
Show code
tbl <- as_rtftable(
  df,
  border        = "tfl",
  col_header    = c("Parameter", "Placebo (N=86)", "Active (N=84)"),
  col_rel_width = c(2, 1, 1),
  row_height_twips = 280L
)
tbl$col_header
#> [[1]]
#> [1] "Parameter" "Placebo (N=86)" "Active (N=84)"See the page & document setup
article for document-wide settings, and ?rtftable for the
full list of per-table options (alignment, per-column/-cell styles and
colours, blank rows, …).
Titles and footnotes
When the source carries a title / subtitle or source notes,
as_rtftables() attaches them to each page as the
rtf_titles / rtf_footnotes attributes, and
rtf_tables() renders them automatically – you do not pass
them again:
doc <- rtf_document() |>
  rtf_section(page = 1, header = NULL, footer = NULL) |>
  rtf_tables(as_rtftables(my_gt_table))   # gt's title/source notes flow through
For a plain data.frame (no metadata), set them on
rtf_tables() with titles = /
footnotes = instead.
Spanning headers from delimited names – header_sep
gt, gtsummary, rtables/tern, flextable and huxtable all carry real
spanning (multi-row) header metadata, which as_rtftables()
reads directly. A plain data.frame has none: the only
place the nesting can live is the column names. A common
producer is ydisctools::pivot_stats_wider(), which spreads
grouping columns into headers joined by ____:
group1 group2 label   cohort1____trt1 cohort1____trt2 cohort2____trt1 cohort2____trt2
Hoge   Sex    Male     11 (55.0)        9 (45.0)        13 (65.0)       7 (35.0)
Hoge   Sex    Female    9 (45.0)       11 (55.0)        7 (35.0)       13 (65.0)
as_rtftables() reconstructs the two-level header from
those names automatically – cohort1 / cohort2
become spanners over their trt1 / trt2 leaf
columns, and the id columns (group1, group2,
label) keep their name on the leaf row:
# `df` produced by ydisctools::pivot_stats_wider(); names use the "____" sep.
as_rtftables(df)            # 2-row header reconstructed by default
header_sep controls the delimiter(s). Its default
recognizes both "____" (ydisctools) and
"___tlang_delim___" (the delimiter tfrmt puts in its
flattened column names), so a data.frame from either tool just works.
Pass your own separator(s) to override, or NULL to keep the
plain one-row header:
as_rtftables(df, header_sep = "::")     # split on your own delimiter
as_rtftables(df, header_sep = NULL)     # disable: use names(df) verbatim
Adjacent columns merge into one spanning cell only when they share
both the label and the same ancestor path, so a
trt1 under cohort1 never merges with a
trt1 under cohort2. An explicit
col_header = (passed through to rtftable())
always wins over the reconstructed one.
With the "____" separator a doubled
separator ("________") splits to an empty middle segment,
i.e. a blank cell at that header level – useful to align a column that
skips an intermediate spanner (e.g. an Overall________n
column sitting beside Drug____Dose____n columns).
This only applies to plain data.frame input; framework tables keep using their own spanning metadata.
Finishing a plain data.frame
A framework table (gt / rtables / …) arrives finished: row-group labels are interleaved, children are indented, headers are labelled. A tidy data.frame is not – it usually looks like “hierarchy columns + statistic columns”. Two finishing tools close that gap without leaving base R.
Hierarchy columns into a stub – stub_cols()
stub_cols() merges hierarchy columns (parent first, leaf
last) into one stub column: each parent value becomes
its own full-width label row, and the leaf rows under it are indented
with non-breaking spaces – the same layout the gt / rtables / tfrmt
adapters emit, produced here from plain columns.
Show code
ae <- data.frame(
  soc = c("", "Cardiac disorders", "Cardiac disorders",
          "Gastrointestinal disorders"),
  pt  = c("Any adverse event", "Atrial fibrillation", "Bradycardia",
          "Nausea"),
  n   = c("9 (6.3%)", "3 (2.1%)", "1 (0.7%)", "5 (3.5%)"),
  stringsAsFactors = FALSE
)

tbl <- stub_cols(ae, vars = c("soc", "pt"),
                 label = "System Organ Class / Preferred Term")
tbl| System Organ Class / Preferred Term | n |
|---|---|
| Any adverse event | 9 (6.3%) |
| Cardiac disorders | |
| Atrial fibrillation | 3 (2.1%) |
| Bradycardia | 1 (0.7%) |
| Gastrointestinal disorders | |
| Nausea | 5 (3.5%) |
Note the "Any adverse event" summary row: its parent
cell is empty (""), so it gets no label row and no
indent – it stays flush left at the top. Label rows hold
NA in the statistic columns, which renders as an empty
cell.
Group-summary rows (the AE pattern)
Adverse-event tables usually carry a group-level
count as well: the total for a System Organ Class, printed on
the SOC row itself, above its indented preferred terms. In the input
that count sits on a row whose leaf is either
NA / "" or a repeat of the parent value.
stub_cols() folds such a row’s statistics onto the
group’s label row – no separate indented leaf – via the
group_summary argument (on by default):
Show code
| soc / pt | n |
|---|---|
| Cardiac disorders | 4 (2.8%) |
| Atrial fibrillation | 3 (2.1%) |
| Bradycardia | 1 (0.7%) |
The 4 (2.8%) SOC total lands on the
Cardiac disorders label row. A leaf that repeats its parent
(e.g. soc = "Cardiac disorders",
pt = "Cardiac disorders") is folded the same way. Control
which markers count with group_summary:
"empty" (the NA / "" leaf),
"parent" (the repeated-parent leaf), both (the default
c("empty", "parent")), or "none" to switch the
folding off. Demographic tables – where the leaf is a statistic name
such as "n" or "Mean (SD)", never
NA and never equal to the parent – are unaffected either
way, so their label rows keep their empty cells and the stats stay on
the indented leaf rows.
Because the output is an ordinary data.frame with baked-in
indentation, everything downstream works unchanged –
group_by = "auto" detects the indent, the group-aware
splits keep a label row with its children and append
" (Cont.)" when a group continues, and
blank_rows = "between_groups" separates the groups:
pages <- as_rtftables(tbl, split = "group_force", max_rows = 20,
                      blank_rows = "between_groups")
With more than two vars each level indents one step
further; a run of the same parent value gets one label row, so
sort the input first (or use sort_by) if
the hierarchy is scattered.
Column label attributes as header labels
Clinical data.frames read via haven / labelled / xportr usually carry
a label attribute on each column. The data.frame branch of
as_rtftables() reads it (the "labels"
read_meta token, on by default): a labelled column uses its
label as the header label, an unlabelled one keeps its name, and an
explicit col_header = still always wins.
Show code
df <- data.frame(param = c("Age", "Sex"), val = c("75.1", "53%"),
                 stringsAsFactors = FALSE)
attr(df$param, "label") <- "Parameter"

as_rtftable(df)$col_header               # "Parameter", "val"
#> [[1]]
#> [1] "Parameter" "val"
as_rtftable(df, read_meta = FALSE)$col_header # NULL -> names(df) used
#> NULLThe labels feed the header_sep reconstruction too, so a
label containing "____" splits into a spanning header
exactly like a delimited column name. stub_cols() preserves
the label attributes of the columns it keeps, and uses the
labels of the columns it merges for its default stub header.
Coming from reporter::create_table()
If you know the reporter package’s table spec, the finishing features map to existing arguments – there is no spec object to build:
| reporter | rtfreporter |
|---|---|
stub(vars) + define(label_row=) /
define(indent=)
|
stub_cols(vars=) before converting |
use_attributes = "label" |
read_meta "labels" token (default on) |
define(visible = FALSE) |
drop_cols |
define(dedupe = TRUE) |
collapse_repeats |
define(blank_after = TRUE) |
blank_rows = blank_rows_by_change(...) |
define(page_break = TRUE) |
split = "by_value", group_col = |
define(align =, width =, label =) |
col_spec / auto_width /
col_header
|
spanning_header() |
header_sep delimited names, or
col_header
|
create_table(first_row_blank =) |
blank_row_first |
create_table(show_cols =) |
subset the data.frame, or drop_cols
|
| sorting |
sort_by / sort_desc
|
Pagination
Everything above is independent of how the table is split into pages.
When the body is longer than one page, control the split with
as_rtftables()s split / max_rows
/ group_col arguments (or a custom function), order the
rows first with sort_by / sort_desc, and hide
a grouping / sort-key column from the output with drop_cols
– all of that is covered in Paginating with
as_rtftables().
See ?as_rtftables for the complete argument reference
and the per-source what is carried table.
Where next
- gt in detail — what is read from a gt table
- Pagination — splitting the result across pages
- The pharmaverse catalog — the same table from five sources
The four recipes (?rtfreporter-recipes) are the same
ground covered as runnable help-page examples: demographics, adverse
events, PK and laboratory, each data-in to RTF-out.